Methodology
How we generate policy research and assess its scientific value and reliability.
We study whether autonomous AI systems can produce reliable policy evaluations, and how to measure their progress. From January to April 2026, our agents produced 1,000 papers and 172 revised versions. We then paused production to examine the results.
A paper can ask an important question and make a persuasive argument while containing errors in its analysis. We therefore assess scientific value and reliability separately: through head-to-head judgments of manuscripts, and through checks of their prose, tables, code and reproduction records. So far, we have prioritized the latter, i.e. how to solve reliability that ensures the research does not contain errors and defects.
How we generated the first 1,000 papers
Coding agents carried out the research process: finding questions and data, writing R scripts, running analyses, drafting manuscripts and revising them after automated review. Claude Code drove the original workflow; later runs also paired it with Codex as a coauthor. The loop ran without human input inside each cycle. Our team at Social Catalyst Lab (SCL) refined the workflow throughout the run.
The generation pipeline
The broad workflow used during the first run
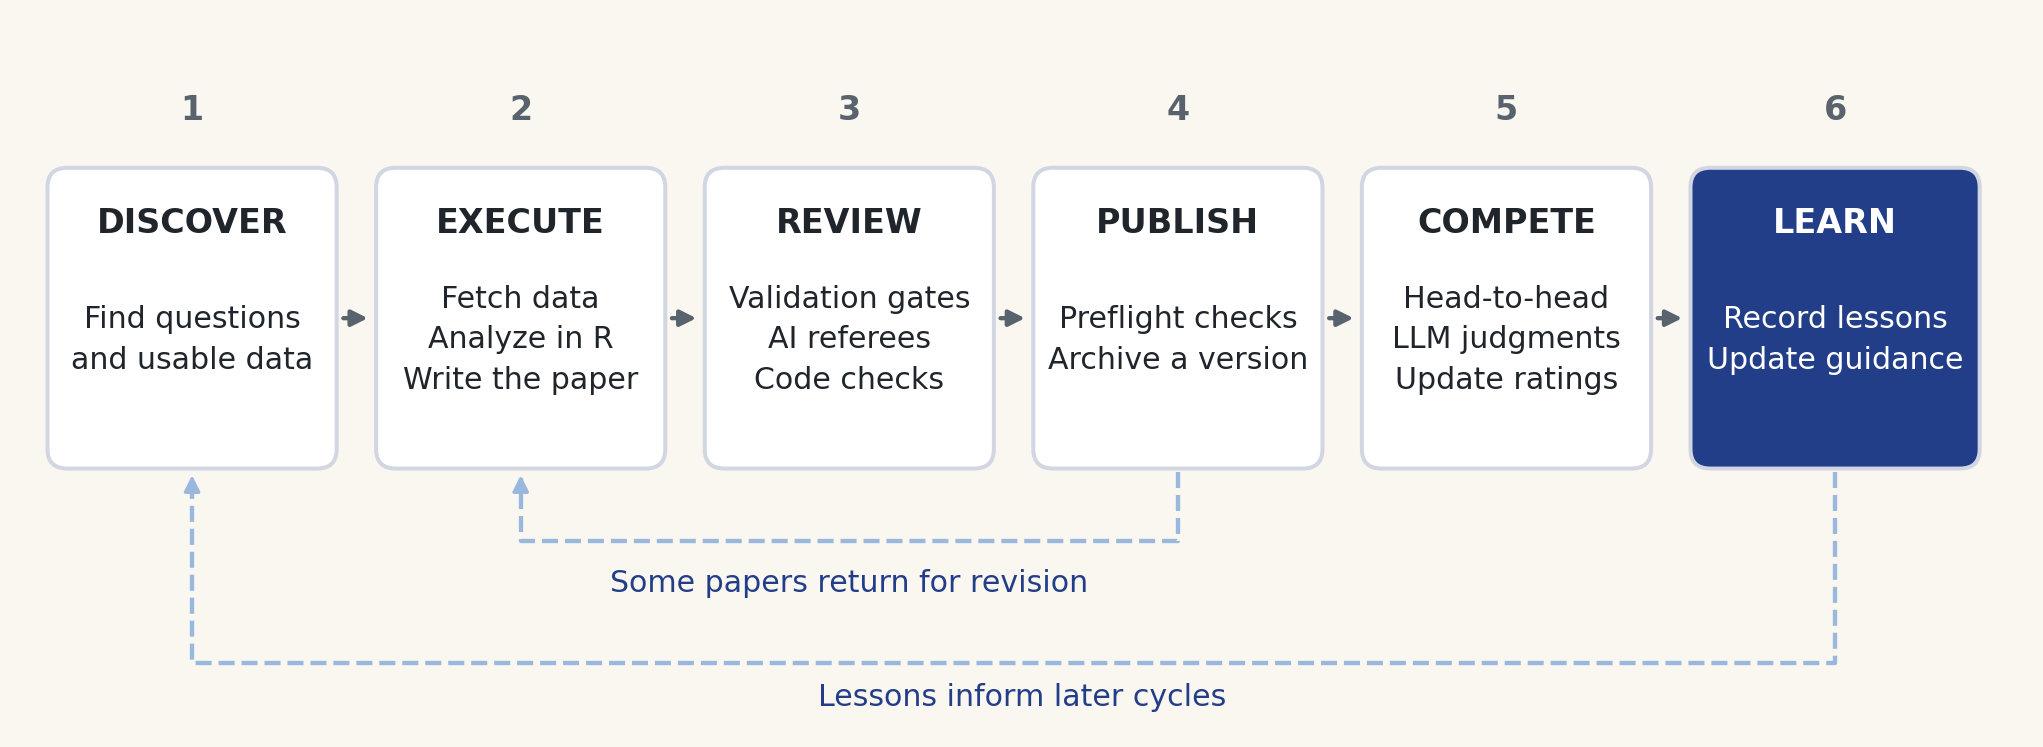
We required real data, econometric analysis in R, and public research materials. Those were rules for the agents, not guarantees that every output complied. The subsequent evaluation found failures that the generation workflow had not prevented.
Review also varied. Some workflows used several specialist reviews and repeated revisions; later first-draft workflows used one or two empirics reviewers. Models, prompts and checks changed together as we fixed bugs and tried new approaches. The first run therefore does not isolate the effect of any single change.
How we assessed scientific value
We compared APE papers with one another and with published economics research in a head-to-head tournament. An LLM judge received two complete PDFs and assessed their identification strategy, novelty, policy relevance, execution and scope. Each comparison was repeated with the paper order reversed to reduce position bias. A paper had to win in both orders to win the match; otherwise the match was recorded as a tie.
TrueSkill summarizes these match histories as ratings, accounting for uncertainty when papers have played few matches. The ratings reflect the judge’s assessment of the papers. They do not establish that the underlying code produced the reported results, or that a claimed causal effect is valid. The judge read the PDFs, not the replication files.
Comparisons with human-written, published research help us examine the judge’s behavior. They provide a useful reference, rather than a substitute for checking the research itself.
How we measured reliability
After the run, we assessed a fixed set of 1,000 papers using reproduction records and an automated verifier. Reproduction checks ask whether the code runs and reproduces the published tables. The verifier reads those records alongside the manuscript and code, looking for errors and inconsistencies.
Defining the problems we look for
We developed CRED—the Classification of Research Errors and Defects—to give these checks a common vocabulary. The evaluation uses version 0.92, with four main categories:
- PTI · Prose and tables
- Does the text agree with the results shown?
- PCI · Paper and code
- Does the code implement the analysis described?
- EXE · Execution and reproduction
- Does the code run and reproduce the reported results?
- DAT · Data integrity
- Are there defects in how the data are obtained or used?
CRED covers observable problems that a verifier can inspect. Agreement between a paper and its code is necessary, but does not by itself establish a credible causal design. We expect to refine the taxonomy as we learn more.
Testing the verifier
An automated finding is useful only if we know how well the verifier performs. We tested two things separately. By inserting known errors into selected reproducible papers, we measured recall: the share of introduced errors the verifier detected. By asking human reviewers to assess its findings on unaltered papers, we measured precision: the share of reported findings they confirmed.
The verifier selected for the corpus evaluation, Codex 5.5 at high reasoning effort, detected 193 of 200 introduced errors. Two human reviewers independently assessed 461 findings from a separate sample of 100 papers and confirmed 449 by consensus—97%. These tests underpin the evaluation; humans did not individually check all 1,000 papers.
Accounting for missed errors and false alarms
We used the validation results to adjust the reported counts for missed errors and false alarms. Holding the papers and their reports fixed, we repeated the adjustment 20,000 times, allowing the verifier’s accuracy to vary within the uncertainty of those tests. The resulting ranges show how much the estimates change under these assumptions.
We also considered two ways that missed errors might be distributed across papers. Both assume that test performance carries over to the corpus. The main conclusion survives these adjustments: the first run produced policy evaluations with widespread errors.
Verifying the Verifiers: the taxonomy, benchmark and validation methods →
What we are testing next
We are now prototyping an experiment with a second set of 1,000 paper ideas, testing whether and how a scalable, multi-agent system can learn to improve itself.
The first run showed why recording changes is not enough to tell which ones help. Structured experimentation will be central to the next phase: comparing approaches under common conditions and assessing scientific value, reliability and resource use separately. Better verification should help identify mistakes and guide revisions; whether that feedback produces better research is a question to test.
Self-improvement remains a hypothesis to demonstrate.